
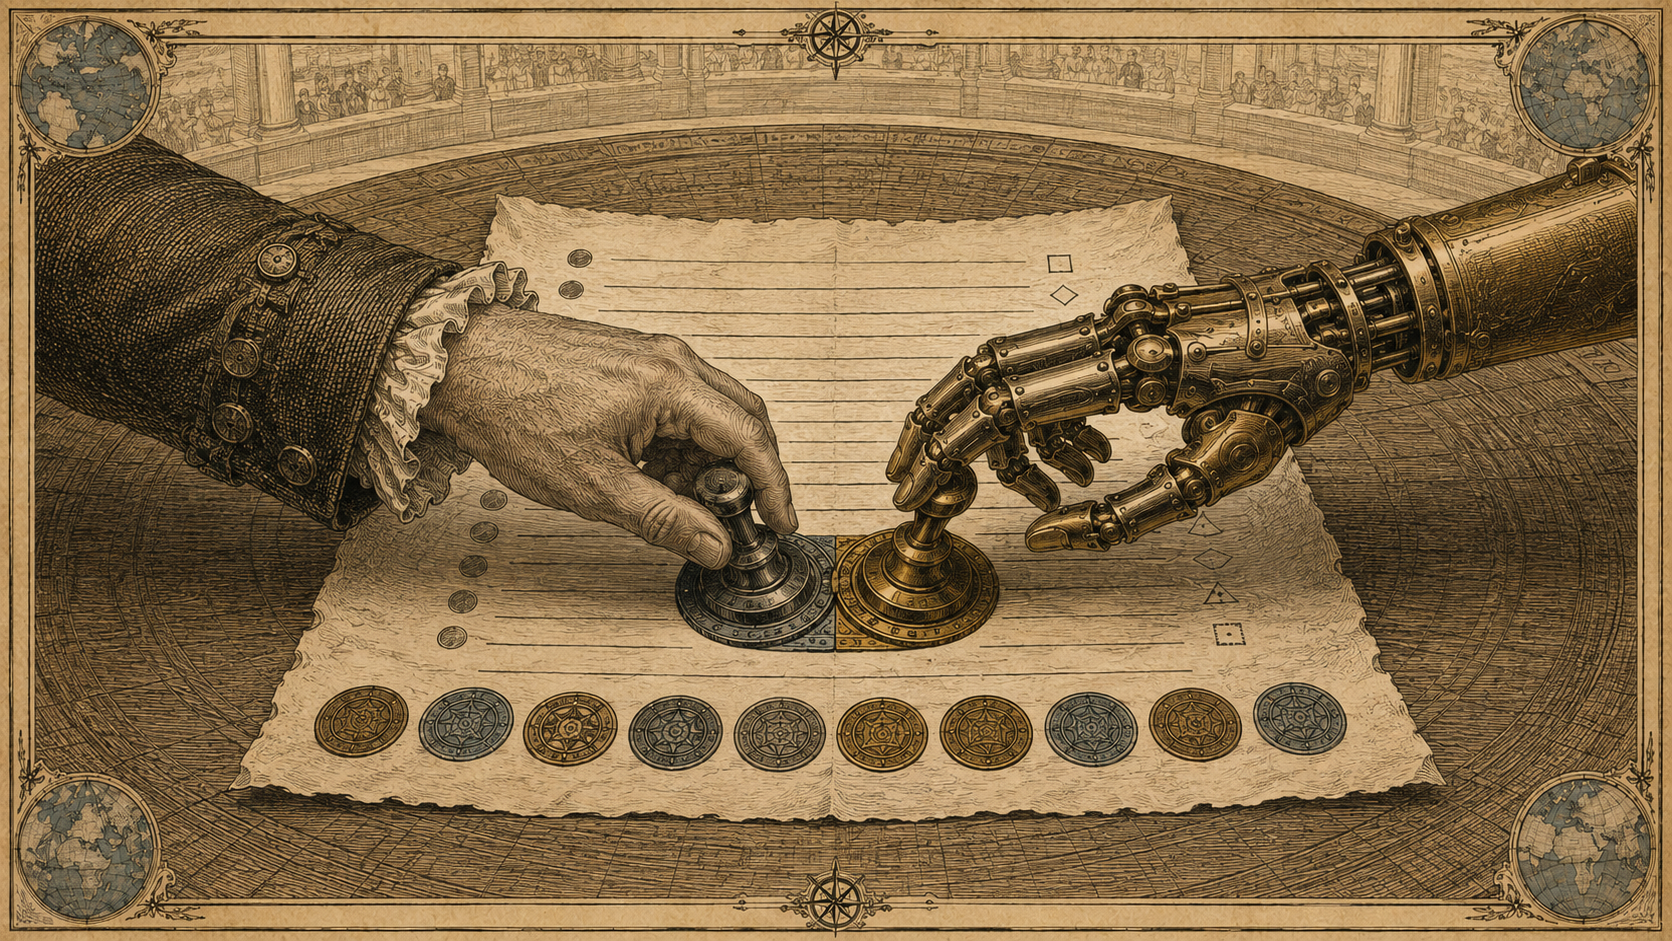
The dangerous agent is not always the one that fails.
It is the one that succeeds at the wrong task: a clean implementation of an inferred requirement, a passing change built against stale architecture, a production action taken inside a boundary nobody thought to state.
That is the uncomfortable part of agentic development. Better models do not remove organisational ambiguity. They make it executable.
We have spent too much of the agent conversation on capability. Can the agent write the code, run the migration, repair the test, operate the service? Those questions matter, but they begin in the middle. Before an agent acts, the organisation has to express what it wants, which version of its own truth applies, what the agent may decide, and what evidence will count as success.
The discipline around that work is agentic development:
Agentic development is the discipline of making intent, organisational context, and boundaries explicit enough for agents to execute safely, and outcomes verifiable enough for the system to decide when the work is done.
The definition is deliberately demanding. It moves attention away from the quality of generated output and towards the quality of the system doing the delegating.
A prompt is not a task contract
A prompt can describe work without defining it.
"Add support for the new partner" sounds clear until the agent has to choose an integration pattern, decide which data may cross the boundary, interpret an old example in the repository, and work out whether a passing unit test is enough to finish.
A task contract closes those gaps before execution. It names the intended outcome, the scope, the non-goals, the constraints, the completion criteria, and the conditions that require escalation. The distinction matters because each item controls a different failure mode.
The outcome prevents the artefact from becoming the goal. The scope and non-goals contain expansion. Constraints state the rules that implementation freedom cannot override. Completion criteria define the evidence the system expects. Escalation conditions stop the agent when the missing decision belongs to someone else.
Proportionality keeps the contract from becoming bureaucracy. A mechanical rename may need a target, a boundary, and a test. A production data migration needs considerably more. Repeated decisions should be encoded once and reused, while the agent stops only where authority or evidence genuinely runs out.
If the contract is materially incomplete, asking is progress. Guessing is not autonomy. It is an unrecorded decision made without authority.
Context is infrastructure
Even a precise task sits inside an organisation that has accumulated architecture decisions, policies, standards, domain language, ownership, incidents, and approved exceptions. Much of that context is scattered across repositories, wikis, tickets, chat, diagrams, and the heads of people who remember why a rule exists.
Humans compensate for this fragmentation. They know which document is stale, which standard applies only to regulated data, and who can resolve a contradiction. An agent receives whichever fragments happen to enter its context window. If the repository demonstrates one pattern and an inaccessible decision record prohibits it, the visible pattern usually wins.
A larger prompt assembled by hand for every task will not solve this. Context has to become organisational infrastructure: shared, governed, and resolved for the work in front of the agent.
Each piece of context needs a scope, authority, owner, provenance, and period of validity. The system also needs rules for precedence, inheritance, exceptions, and conflicts. Without those properties, retrieval can find more material while leaving the agent with no defensible way to decide which material governs.
This is why architecture must become usable context, not merely readable documentation. The agent should receive the decisions relevant to its task, know why they apply, and encounter a stop condition when authoritative sources disagree.
Context management belongs in the control plane.
Autonomy ends at the decision boundary
An agent needs room to work. Delegation has little value if a human must approve every implementation detail. But freedom inside a task is different from authority over the task.
The agent may choose a local refactoring, test structure, or implementation sequence when those choices stay inside the approved space. It must not invent business meaning, policy, architectural exceptions, risk acceptance, or a new requirement. Those are decision boundaries because crossing them changes more than the means of delivery. It changes what the organisation has authorised.
A useful boundary answers two questions:
- What may the agent decide for itself?
- What must cause it to stop?
The second question is usually neglected. Teams describe the happy path, grant tools and credentials, then rely on the model to recognise when a situation has become unusual. A safe loop makes unusual conditions explicit: missing authority, stale context, contradictory sources, an action outside the permitted environment, an irreversible operation, or ambiguity that could materially change the result.
Autonomy should also be bounded by scope, permissions, time, cost, environment, and blast radius. Prefer changes that are small, observable, and reversible. Wider autonomy should be earned with evidence from narrower loops, not granted because a demonstration looked convincing.
Completion belongs to the system
An agent can report that it finished. It cannot be the only judge.
Execution and verification have different jobs. The executor proposes a change and gathers observations. Independent checks decide whether the expected behaviour and constraints have been satisfied. Independence does not always require a second model or a human reviewer. It can come from tests, policy evaluation, schema validation, a deployment health check, reconciliation against the requested state, or another signal that the executor cannot redefine to suit its output.
This distinction becomes more important as the cost of producing an attempt falls. As argued in Code Is Cheap. Verification Is the New Scarcity, a plausible change is only an intermediate product. The useful result is a verified outcome.
"Done" should therefore be a collection of evidence mapped to the task contract. It should show:
- which checks ran and what they established;
- which observations were made in the target environment;
- which assumptions remained necessary;
- which constraints were evaluated;
- which risks remain;
- and whether the intended outcome, rather than merely the requested artefact, now exists.
The mapping matters. A green test suite is strong evidence for the behaviours it exercises and no evidence for the ones it does not. A successful deployment proves that software reached an environment, not that a customer outcome changed. Evidence earns trust only when the system can say what each result proves.
Guardrails must change what happens next
Written expectations are useful. They explain intent, teach people, and preserve reasoning. They are weak controls when the system can ignore them without consequence.
An executable guardrail changes the next available action. It lets the agent continue, directs it towards an approved repair, stops the loop, or escalates the decision. That is more useful than a warning because it connects the rule to execution.
Consider the difference between these messages:
This change may violate the data policy.
and:
This change introduces customer data without an approved handling rule. Remove the field, apply an approved rule, attach an authorised exception, or stop.
The first message transfers interpretation back to the agent. The second defines the boundary and the permitted recovery paths.
Critical controls should be enforced by the environment wherever possible. Permissions should prevent access that the task does not require. Policy checks should block prohibited changes. Destructive actions should require stronger authority than reversible ones. Cost and time limits should end runaway loops. Logs should preserve what the agent attempted, which context it received, and why the system allowed the next step.
Instructions still matter, but they should not carry a load the surrounding system is capable of enforcing.
Put humans where judgment changes the outcome
"Human in the loop" is often treated as a complete safety design. It is only a location.
A human who clicks approve on routine agent actions can become a slower, less consistent guardrail. The organisation keeps the latency of manual work without necessarily gaining careful judgment. As volume rises, approval becomes a queue and the queue becomes pressure to wave changes through.
Humans are most useful where their judgment can alter the result: setting intent, choosing between real trade-offs, approving exceptions, interpreting novel risk, and resolving contradictions the system has no authority to settle. They should design the loop and improve its controls, not repeat decisions that the organisation already knows how to encode.
Human accountability remains. The difference is a more specific role: people own the consequential decisions, while the system handles repeatable enforcement and produces the evidence those people need.
This discipline will slow some actions. That is intentional when authority is missing, the evidence is weak, or the action cannot be reversed. Everywhere else, encoded decisions should remove repeated negotiation and let routine work move without waiting for another approval.
Every correction is a design input
An agent makes a mistake. A reviewer explains the issue. The agent repairs the change. The immediate task moves on, but the organisation has learned almost nothing if the explanation disappears with the review thread.
Repeated corrections should become system improvements. A missing rule belongs in governed context. A recurring defect belongs in a test. An unsafe option belongs behind a guardrail. A confusing interface belongs in the tool contract. A common ambiguity belongs in the task template. A policy exception needs an owner, a scope, and an expiry condition.
This is how autonomy expands without becoming faith. The organisation observes where the loop fails, changes the environment, then grants more room when the evidence supports it. The agent gets more capable because the system around it gets less ambiguous.
Measure safe outcomes, not agent activity
Agent activity is easy to count: prompts sent, tokens consumed, code generated, pull requests opened, tickets closed. Those measures describe usage. Value starts with what the activity changed.
The useful measures follow the work to its result. How long did it take to reach a verified outcome? How much rework did the first attempt create? Which defects escaped? What operational impact followed? Where did a human intervention materially change the decision? Did the system learn from the failure, or will the same correction be purchased again?
These measures keep the organisation from rewarding motion for its own sake. A loop that produces twice as many changes and twice as much review load has not doubled engineering capacity. It has moved the bottleneck.
The manifesto
The principles are also available as a standalone reference: The Agentic Development Manifesto.
We value:
- verified outcomes over generated output;
- explicit intent and governed context over plausible interpretation;
- executable guardrails over written expectations;
- evidence-driven loops over one-shot delegation;
- human judgment over human rubber-stamping.
The items on the right still have value. Trustworthy delegation depends on the items on the left.
These values lead to ten principles:
- Start with a clear task contract.
- Manage context as organisational infrastructure.
- Separate execution from verification.
- Allow no completion without evidence.
- Make guardrails constrain, not merely advise.
- Do not let agents improvise across decision boundaries.
- Grant bounded and reversible autonomy.
- Put humans where judgment changes the outcome.
- Turn every failure into system improvement.
- Measure the flow of safe outcomes.
The list defines a design standard for the organisation delegating the work, not another set of instructions for the agent.
Before that organisation delegates, it should be able to answer eight questions:
What outcome is expected? What context applies? Who owns that context? What may the agent decide? What must it never invent? What evidence proves success? What makes it stop? Who owns the result?
If those answers live only in someone's head, the agent does not have them. If they exist only as prose, the system may not enforce them. If the evidence is produced by the same loop that decides whether it is sufficient, completion remains a claim.
The organisation provides the context.
The agent creates motion.
The system turns motion into evidence.
The standard turns evidence into trust.
The Conversation
Members can comment on every field note.
Subscribe to join the discussion and add your perspective to the record.